 Plato’s Cave (Jan Pietersz Saenredam after Cornelis Cornelisz van Haarlem 1604)
You are viewing this on a mobile device, but SITP is best viewed on a desktop — the book includes various multimedia lecture videos, visualizers, any tufte-style sidenotes with many external hyperlinks to other resources.
II. Neural Networks
Deep Neural Networks
Welcome young hacker! Glad to see you here. The whimsical whirlwind tour known as The Structure and Interpretation of Tensor Programs (SITP) started with Part I. Elements of Networks where we developed a solid breadth of foundation in the computational, mathematical, and performance-oriented perspectives of the statistical approach to machine learning. By now, although we’ve “only” trained what amounts to a single layer network, we are now more than comfortable in the stochastic and infinitely continuous language of software 2.0. That is, although using the precise tools of mathematics to specify architectures, loss functions, and optimizers, the essence of the discipline is more akin to synthetic chemistry or microbiology which grow chemicals and cells. In Part II. Neural Networks, we simply continue where we left off.
representation learningrepresentation learning universal approximatorsuniversal approximators double descentdouble descent
Namely, in §3.1.2 From Localist to Distributional Representations, we cover XYZ and in §3.1.3 From Linear Perceptrons to Non-Linear Multi Layer Perceptrons. we increase the expressivity of model architecture from linear perceptrons otherwise known as single-layer networks to non-linear multi-layer perceptronsmulti-layer perceptron or deep neural networksdeep neural network. Moreover, because deep networks are no longer linear, in §3.1.4 From Direct to Iterative Optimization we transition from from direct optimizatio methods that solve for the exact solution to iterative ones that solve for approximate solutions.
After Part II. Neural Networks, we will be ready for Part III. Scaling Networks where we finally complete our quest in building our own
language model such as ChatGPT by following Nanochat and subsequently, our own deep learning framework capable of running said language model like PyTorch 2,
by implementing 
borscht.compile() and borscht.distributed().
Part three follows the 2020-2025 time period of what is colloquially known as the
the age of scalingage of scaling
where researchers focused on scaling up the generality of transformer architecture
by adding additional phases after pre-trainingpre-training stochastic parrots.
That is, the mid-trainingmid-training
and post-trainingpost-training phases
which respectively produce helpful assistantsassistants with
reinforcement learning from human feedback and slow thinking reasonersreasoners with verifiable rewards.
But before we get there we have some work to do.
Let’s go.
II. Table of Contents
- 3. Self-Supervised Pre-training with Deep Networks
- Intermezzo Three: The Language of Differentiable Programming
- 4. The Engine of Automatic Differentiation
3. Self-Supervised Pre-Training with Deep Networks
3.1 Learning Static Representations with FFNs
In which we transition from machine learning to deep learning, which focuses on learning distributional representations automatically with deep nets; introduce such deep nets as multi-layer perceptrons, the non-linear extensions of linear models with the ReLU and Embed primitives; transition our optimization techniques to handle non-linear functions with iterative descent methods.
3.1.1 From Feature Engineering to Representation Learning
Table of Contents (§3.1 Learning Representations with FFNs)
Deep learningdeep learning builds off from such foundation, namely, programming of software 2.0 with the three step process of selecting a model architecture, scoring it with a loss, and optimizing such loss. However, deep learning focuses on the class of models known as deep neural networks or multi-layer perceptrons that introduce many layers of non-linearities that make them well-suited for learning representationsrepresentation learningSee (Bengio et al., 2012) and (LeCun et al., 2015).
localist representationlocalist representation distributional representationdistributional representation
Localist representations such as one hot vectors are used to program the software 2.0 of machine learning, whereas distributional representationsdistributional representation such as embeddingsembeddings are used to program the software 2.0 of deep learning. In this chapter, we will learn about the neural network primitive of Embed.
Stanford CS224N: NLP with Deep Learning | Lecture 1 - Intro and Word Vectors
Stanford CS224N: NLP with Deep Learning | Lecture 2 - Word Vectors and Language Models
Namely, in §3.1.2 From Localist to Distributional Representations, we cover XYZ and in §3.1.3 From Linear Perceptrons to Non-Linear Multi Layer Perceptrons. we increase the expressivity of model architecture from linear perceptrons otherwise known as single-layer networks to non-linear multi-layer perceptronsmulti-layer perceptron or deep neural networksdeep neural network. Moreover, because deep networks are no longer linear, in §3.1.4 From Direct to Iterative Optimization we transition from from direct optimizatio methods that solve for the exact solution to iterative ones that solve for approximate solutions.
| 2.0 goal | 2.0 method (Part I) | 2.0 method (Part II) |
|---|---|---|
| evaluation | next-token prediction with stochastics of probability theory and compression of information theory | next-token prediction with stochastics of probability theory and compression of information theory |
| architecture | linear single-layer perceptron with dimensionality of linear algebra | non-linear multi-layer perceptron with dimensionality of linear algebra |
| optimizers | direct solvers with linear systems of linear algebra | iterative solvers with approximation of differential calculus |
| systems | speed of light acceleration with rooflines of cpus | speed of light acceleration with rooflines of gpus |
In §3. Self-Supervised Pre-Training with Deep Networks, we will implement different neural network architectures that all express various inductive biasesinductive biases. Such inductive biases were all explored during the 2012-2019 time period of what is coloquially known as the age of researchage of research. Keeping the goal of next-token prediction constant, we start from the standard feedforward neural networksFFN (FFN), and then transition to more novel architectures such as convolutional neural networksCNN (CNN), recurrent neural networksRNN (RNN), and finally, generative pre-trained transformersGPT (GPT), specifically by reproducing GPT-2Presented in Language Models are Unsupervised Multitask Learners (Raford et al. 2019) following Nanogpt. Because deep neural networks are no longer linear functions of their parameters, we will need to transition from direct methods to iterative ones with descent-based searches. Starting from gradient descentgradient descent, momentummomentum, weight decayweight decay, AdamWAdamW.
Then, in §4. The Engine of Automatic Differentiation,
you will evolve the implementation of borscht from a numerical linear algebra library like Numpy
from §2. The Multidimensional Parallelized Tensor into
a full blown batteries-included deep learning framework like TORCH which will be able to run the training and inference of the said nets just trained in §3.
This means implementing the optimizers for neural network primitives whose evaluations are accelerated with massively parallel processors known as graphics processing unitsGPU (GPUs)
and whose gradients are automatically evaluated with an automatic differentationautomatic differentiation engine.
Consult last few chapters of (Jurafsky and Martin 2026)If Jurafsky and Martin is not your cup of tea, take a look at (Eisenstein 2018)., and (Bishop 2025)Similarly, you can also take a look at (Goodfellow et al., 2017) for deep learning.
junk
Newton’s classical mechanics must be understood before Einsten’s general relativity.
Similarly, so too of Rosenblatt’s machine learning before that of Bengio, Hinton, and LeCun’s deep learning.
First, we understand that language models such as Nanogpt, ChatGpt, and Claude
are specified as next-token predictors which although decide on a final classifying token for the given context (todo ?), have a step of inference by modeling language stochastically with a conditional random variable endowed with a probability distribution where such distribution corresponds to an array
which can be represented by a borscht.Tensor with .shape of (V).
This was the first step in our transition from classical software 1.0 to the jazz of software 2.0,
namely, by transitioning from variables to random variables in §1.1 From Certain to Uncertain Knowledge.
(expand with coterell formalization)
Second, we understanding that such language models probabilistically specified as autoregressive next-token predictors are implemented by estimating the parameterization of their functions with weights and bias so that where is a function that takes in a one-hot vector as input (expand, context?), evaluates the weighted sum with which is the standard inner product of the dot product, and then either uses the dot product directly in the case of linear regression with §1.3 Parameterizing Classification with Linear Regression or further composes the output with a squashing function in §1.4 Parameterizing Classification with Logistic Regression. In either case, both models are specified dimensionally, and, in the case of linear models, can be implemented with the direct optimization of linear algebra’s linear systems as well
3.1.2 From Linear Perceptrons to Non-Linear Multi Layer Perceptrons
Table of Contents (§3.1 Learning Representations with FFNs)
Linear models such as a single layer of perceptrons are used to program the software 2.0 of machine learning, whereas non-linear modelsnon-linear models such as multi-layer perceptronsmulti-layer perceptrons are used to program the software 2.0 of deep learning. We will compose the primitives of Embed, Linear, and RelU together to form a deep neural network.
- wed sep.23 after the 3.1 source of flow
- work on architecture 3.1.3 (merge the various representations) and optimizers 3.1.4
- including synthesis from intermezzo
Recall that the task of house price prediction and sentiment classification which can be modelled by functions of the form and respectively. The simplest inductive bias was made, in a which a linear relationship was assumed to hold between the input and output spaces, and where the output was subsequently modeled as an inner product between an input vector and a weight vector. For the case of regression, we have , and for the case of classification, we have , todo:glm,exp. The key entry point into the function class of deep neural networksdeep neural network Stanford CS109 | Deep Learning | Lecture 25
Stanford CS229 Machine Learning | Lecture 7: Neural Networks (Architecture)
Stanford CS229 Machine Learning | Lecture 13: LLMs, Next-Word Prediction Loss
is that of logistic regression, because the log odds produced by the inner product (which are indeed affine) required a mapping into a valid probability via sigmoid function , where which is in fact not linear nor affine.
But what is a neural network? | Deep learning chapter 1 (3Blue1Brown 2017)
The next natural question to ask then is whether the logistic regression model is considered a deep neural network? The answer is that technically yes, it can be considered a degenerative deep neural network with hidden layersIn the same way that a list can be considered a degenerative binary tree or graph. These so-called hidden layers automate the construction of the representation through learning, so that the model not only discovers the mapping from representation to output, but also the representation itself. The functions of deep neural networks will take the form of with being a linear classifier on feature extractor , where is the number of compositional layers, and each intermediate function has the form of . Each hidden layer successively and gradually lifts the complexity and abstraction of the data’s representationChris Olah, cofounder of Anthropic and the lead of it’s interpretability research wrote an excellent article on how software 2.0’s representation learning loosely correspond to software 1.0’s types in Neural Networks, Types, and Functional Programming.
Together, these two aspects of learning non-linear, representations form the essence of deep learning.


Let’s now turn out attention to the function bodies of these ’s with a deep neural netork of hidden layer, carrying out the task of price regression and sentiment classification so that has the form . With the statistical learning foundation from part one, we will simply present the forward pass , the loss function , and the backward pass .
Forward Pass
The functions of deep neural networks will take the form of with being a linear classifier on feature extractor
where is the number of compositional layers, and each intermediate function has the form of .
Loss Function
Backward Pass
missing notebook: /opt/build/repo/sitp/notebooks/3.1_ffn.ipynb
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Proin finibus interdum arcu, ut venenatis dolor rutrum eget. Nulla nec urna tellus. Donec sollicitudin hendrerit sollicitudin. Proin sagittis, velit commodo congue rhoncus, metus turpis hendrerit nisi, a accumsan quam ante ultricies sem. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Ut aliquet ut justo non posuere. Quisque in rutrum nunc. Phasellus vehicula tortor mi, vehicula placerat diam ultrices eget. Aliquam et consequat eros, quis fermentum tortor. Sed eu nisl viverra, auctor velit vel, elementum ante. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Proin aliquet metus sit amet nulla cursus maximus in feugiat mi. Praesent vehicula magna sed scelerisque elementum. Nulla euismod rutrum turpis sed hendrerit.
3.1.3 From Direct to Iterative Optimization
Table of Contents (§3.1 Learning Representations with FFNs)
Direct optimization such as solving linear systems of equations with least squares is used to program the software 2.0 of machine learning, whereas iterative optimizationiterative optimization such as gradient descentgradient descent via backpropagationbackpropagation Stanford CS229 Machine Learning | Lecture 8: Neural Networks 2 (Backprop) Stanford CS224N: NLP with Deep Learning | Lecture 3 - Backpropagation, Neural Network is used to program the software 2.0 of deep learning. In this chapter, we will learn how to instantiate a neural network by selecting a specific instance of it’s parameters by solving the optimization problem .
By now you understand that the discipline of machine learning recovers parameterized functions from dataset , and in the particular case of language modeling, such input space and output space is the set of all sentences and the set of all words , the regime of learning is that of classification. That is, a language model is a next token predictor which generates sequences by chaining the classifications of individual words with the product rule.
In §1. Self-Supervised Sequence Learning with Single-Layer Networks, we became familar with two approaches to model , namely the bigram and logistic regression models corresponding to a stochastic matrix and a squashed weighted sum respectively, which in turn are composed with decision boundary to decide on the final output . That is, and (expand). Particularly with the parameterized logistic regression , we specified a loss function (expand, loss.mle) of such parameters and optimized it with iterative reweighted least squares. Before we move onto increasing the expressivity of our models from single layer networks to multi layer networks, let us first introduce a new method of optimizing the loss function, namely gradient descentgradient descent which is the fundamental optmization technique for training neural nets. It wouldn’t be an overstatement to call it the of deep learning.
The intuition behind gradient descent is quite simpleIn the case of and which correspond to our physical intuition. We will see how this breaks down in higher dimensions ..
(pseudocode)
(borschtcode borscht.backwards())
missing notebook: /opt/build/repo/sitp/notebooks/3.1_ffn.ipynb
3.2 Iterative Optimization
In which we delve deeper into foundations of gradient-based iterative optimization, building ourselves up to the AdamW optimizer.
3.2.1 Taylor Series and their Derivatives, Gradients, and Hessians
Lorem ipsum MIT 6.7960 Deep Learning: Lec 07. Scaling Rules for Optimization dolor sit amet, consectetur adipiscing elit. Proin finibus interdum arcu, ut venenatis dolor rutrum eget. Nulla nec urna tellus. Donec sollicitudin hendrerit sollicitudin. Proin sagittis, velit commodo congue rhoncus, metus turpis hendrerit nisi, a accumsan quam ante ultricies sem. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Ut aliquet ut justo non posuere. Quisque in rutrum nunc. Phasellus vehicula tortor mi, vehicula placerat diam ultrices eget. Aliquam et consequat eros, quis fermentum tortor. Sed eu nisl viverra, auctor velit vel, elementum ante. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Proin aliquet metus sit amet nulla cursus maximus in feugiat mi. Praesent vehicula magna sed scelerisque elementum. Nulla euismod rutrum turpis sed hendrerit.
3.2.2 First Order Optimization
3.2.3 Second Order Optimization
3.2.4 Momentum
3.2.5 Weight Decay
3.3 Learning Representations with CNNs
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Proin finibus interdum arcu, ut venenatis dolor rutrum eget. Nulla nec urna tellus. Donec sollicitudin hendrerit sollicitudin. Proin sagittis, velit commodo congue rhoncus, metus turpis hendrerit nisi, a accumsan quam ante ultricies sem. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Ut aliquet ut justo non posuere. Quisque in rutrum nunc. Phasellus vehicula tortor mi, vehicula placerat diam ultrices eget. Aliquam et consequat eros, quis fermentum tortor. Sed eu nisl viverra, auctor velit vel, elementum ante. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Proin aliquet metus sit amet nulla cursus maximus in feugiat mi. Praesent vehicula magna sed scelerisque elementum. Nulla euismod rutrum turpis sed hendrerit.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Proin finibus interdum arcu, ut venenatis dolor rutrum eget. Nulla nec urna tellus. Donec sollicitudin hendrerit sollicitudin. Proin sagittis, velit commodo congue rhoncus, metus turpis hendrerit nisi, a accumsan quam ante ultricies sem. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Ut aliquet ut justo non posuere. Quisque in rutrum nunc. Phasellus vehicula tortor mi, vehicula placerat diam ultrices eget. Aliquam et consequat eros, quis fermentum tortor. Sed eu nisl viverra, auctor velit vel, elementum ante. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Proin aliquet metus sit amet nulla cursus maximus in feugiat mi. Praesent vehicula magna sed scelerisque elementum. Nulla euismod rutrum turpis sed hendrerit.
3.4 Learning Representations with RNNs
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Proin finibus interdum arcu, ut venenatis dolor rutrum eget. Nulla nec urna tellus. Donec sollicitudin hendrerit sollicitudin. Proin sagittis, velit commodo congue rhoncus, metus turpis hendrerit nisi, a accumsan quam ante ultricies sem. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Ut aliquet ut justo non posuere. Quisque in rutrum nunc. Phasellus vehicula tortor mi, vehicula placerat diam ultrices eget. Aliquam et consequat eros, quis fermentum tortor. Sed eu nisl viverra, auctor velit vel, elementum ante. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Proin aliquet metus sit amet nulla cursus maximus in feugiat mi. Praesent vehicula magna sed scelerisque elementum. Nulla euismod rutrum turpis sed hendrerit.
class RNNCell(nn.Module):
  """
  the job of a 'Cell' is to:
  take input at current time step x_{t} and the hidden state at the
  previous time step h_{t-1} and return the resulting hidden state
  h_{t} at the current timestep
  """
  def __init__(self, config):
    super().__init__()
    self.xh_to_h = nn.Linear(config.n_embd + config.n_embd2, config.n_embd2)

  def forward(self, xt, hprev):
    xh = torch.cat([xt, hprev], dim=1)
    ht = F.tanh(self.xh_to_h(xh))
    return ht

class RNN(nn.Module):
  def __init__(self, config, cell_type):
    super().__init__()
    self.block_size = config.block_size
    self.vocab_size = config.vocab_size
    self.start = nn.Parameter(torch.zeros(1, config.n_embd2)) # the starting hidden state
    self.wte = nn.Embedding(config.vocab_size, config.n_embd) # token embeddings table
    if cell_type == 'rnn':
        self.cell = RNNCell(config)
    elif cell_type == 'gru':
        self.cell = GRUCell(config)
    self.lm_head = nn.Linear(config.n_embd2, self.vocab_size)

  def get_block_size(self):
    return self.block_size

  def forward(self, idx, targets=None):
    device = idx.device
    b, t = idx.size()

    # embed all the integers up front and all at once for efficiency
    emb = self.wte(idx) # (b, t, n_embd)

    # sequentially iterate over the inputs and update the RNN state each tick
    hprev = self.start.expand((b, -1)) # expand out the batch dimension
    hiddens = []
    for i in range(t):
      xt = emb[:, i, :] # (b, n_embd)
      ht = self.cell(xt, hprev) # (b, n_embd2)
      hprev = ht
      hiddens.append(ht)

    # decode the outputs
    hidden = torch.stack(hiddens, 1) # (b, t, n_embd2)
    logits = self.lm_head(hidden)

    # if we are given some desired targets also calculate the loss
    loss = None
    if targets is not None:
      loss = F.cross_entropy(logits.view(-1, logits.size(-1)), targets.view(-1), ignore_index=-1)

    return logits, loss
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Proin finibus interdum arcu, ut venenatis dolor rutrum eget. Nulla nec urna tellus. Donec sollicitudin hendrerit sollicitudin. Proin sagittis, velit commodo congue rhoncus, metus turpis hendrerit nisi, a accumsan quam ante ultricies sem. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Ut aliquet ut justo non posuere. Quisque in rutrum nunc. Phasellus vehicula tortor mi, vehicula placerat diam ultrices eget. Aliquam et consequat eros, quis fermentum tortor. Sed eu nisl viverra, auctor velit vel, elementum ante. Orci varius natoque penatibus et magnis dis parturient montes, nascetur ridiculus mus. Proin aliquet metus sit amet nulla cursus maximus in feugiat mi. Praesent vehicula magna sed scelerisque elementum. Nulla euismod rutrum turpis sed hendrerit.
3.5 Learning Dynamic Representations with GPTs
In which we transition from long-range depencies of recurrent neural nets to the ___ of transformer-based neural nets.
3.5.1 Dynamic Embeddings with Attention
Table of Contents (§3.5 Learning Representations with GPTs)
Attention is all you need. static embeddingsstatic embeddings dynamic embeddingsdynamic embeddings Stanford CS229 Machine Learning Lecture 14: Transformers, In-Context Learning
Stanford CME295 Transformers & LLMs | Lecture 1 - Transformer
Stanford CS25: V2 I Introduction to Transformers w/ Andrej Karpathy
fluffy blue creature roamed the verdant forest. Lorem ipsum dolor sit amet, consectetur adipiscing elit, sed do eiusmod tempor incididunt ut labore et dolore magna aliqua. Ut enim ad minim veniam, quis nostrud exercitation ullamco laboris nisi ut aliquip ex ea commodo consequat. Duis aute irure dolor in reprehenderit in voluptate velit esse cillum dolore eu fugiat nulla pariatur. Excepteur sint occaecat cupidatat non proident, sunt in culpa qui officia deserunt mollit anim id est laborum.
Lorem ipsum dolor sit amet, consectetur adipiscing elit, sed do eiusmod tempor incididunt ut labore et dolore magna aliqua. Ut enim ad minim veniam, quis nostrud exercitation ullamco laboris nisi ut aliquip ex ea commodo consequat. Duis aute irure dolor in reprehenderit in voluptate velit esse cillum dolore eu fugiat nulla pariatur. Excepteur sint occaecat cupidatat non proident, sunt in culpa qui officia deserunt mollit anim id est laborum.
microgpt: https://gist.github.com/karpathy/8627fe009c40f57531cb18360106ce95
class Block(nn.Module):
    def __init__(self, config):
        super().__init__()
        D, H = config.n_embd, config.n_head
        self.ln_1 = nn.LayerNorm(D)
        self.attn = MHA(config)
        self.mlp = FFN(config) # .mlp for HF
        self.ln_2 = nn.LayerNorm(D)

    def forward(self, X_BTD):
        # residuals:
        # - (He et al. 2015 https://arxiv.org/abs/1512.03385)
        # - (Elhage et al. 2021 https://transformer-circuits.pub/2021/framework/index.html)
        X_BTD = X_BTD + self.attn(self.ln_1(X_BTD))
        X_BTD = X_BTD + self.mlp(self.ln_2(X_BTD))
        return X_BTD

class MHA(nn.Module):
    def __init__(self, config):
        super().__init__()
        T, D, H = config.block_size, config.n_embd, config.n_head
        assert D % H == 0

        self.H = H

        self.c_attn = nn.Linear(D, 3 * D)
        self.c_proj = nn.Linear(D, D)
        self.c_proj.GPT2_SCALE_INIT = 1
        self.register_buffer('bias', torch.tril(torch.ones(T, T)).view(1, 1, T, T)) # tril -> bias for HF

    def forward(self, X_BTD):
        B,T,D = X_BTD.shape
        H = self.H
        # 1. project to learned QKV subspaces Q=WqX, K=WkX, V=WvX
        Wq_DK, Wk_DK, Wv_DK = self.c_attn(X_BTD).split(D, dim=2)
        Q_BHTK, K_BHTK, V_BHTK = Wq_DK.view(B, T, H, D // H).transpose(1, 2), Wk_DK.view(B, T, H, D // H).transpose(1, 2), Wv_DK.view(B, T, H, D // H).transpose(1, 2)

        # 2. evaluate scores A(QKV) = softmax(QK^T/sqrt(d_k))V
        # A_BHTT = Q_BHTK @ K_BHTK.transpose(-2, -1) * (1.0 / math.sqrt(K_BHTK.size(-1)))
        # A_BHTT = A_BHTT.masked_fill(self.bias[:, :, :T, :T]==0, float('-inf'))
        # A_BHTT = F.softmax(A_BHTT, dim=-1) # todo, when dim=-1?
        # S_BHTD = A_BHTT @ V_BHTK
        S_BHTD = F.scaled_dot_product_attention(Q_BHTK, K_BHTK, V_BHTK, is_causal=True)

        # 3. contextualize the embeddings
        S_BTD = S_BHTD.transpose(1, 2).contiguous().view(B, T, D) # performs cat
        S_BTD = self.c_proj(S_BTD)

        return S_BTD
3.5.2 Storing Facts with FFN
Table of Contents (§3.5 Learning Representations with GPTs)
Storing facts consectetur adipiscing elit. Donec aliquam varius mi, pharetra scelerisque nulla vehicula ut. Cras ac faucibus dolor. Nunc tempus efficitur ultricies. Nullam non fermentum elit, et tincidunt ante. Donec hendrerit metus ac urna semper, in facilisis leo egestas. Integer sit amet quam ultrices, dapibus sem a, volutpat velit. Pellentesque eget ipsum consequat sem luctus blandit a et nibh. Mauris gravida felis ut dignissim volutpat. Quisque volutpat pulvinar enim in venenatis. Integer posuere tincidunt leo vel congue. Sed ex velit, posuere ut nibh nec, ultrices malesuada nibh. Fusce scelerisque mollis neque id fringilla. Etiam rhoncus quam a leo ultrices rutrum non vitae est. Donec bibendum, arcu sagittis consequat vestibulum, lectus elit bibendum libero, non rhoncus lorem lorem a neque. Sed ex felis, rutrum non consequat eget, tincidunt ac lacus.
class FFN(nn.Module):
    def __init__(self, config):
        super().__init__()
        D = config.n_embd
        self.c_fc = nn.Linear(D, 4*D) # projecting up to extract features from context embeddings
        self.gelu = nn.GELU(approximate='tanh') # (Hendrycks et al. https://arxiv.org/abs/1606.08415)
        self.c_proj = nn.Linear(4*D, D) # projecting back down to residual pathway
        self.c_proj.GPT2_SCALE_INIT = 1

    def forward(self, X_BTD):
        X_BT4D = self.c_fc(X_BTD)
        X_BT4D = self.gelu(X_BT4D)
        X_BTD = self.c_proj(X_BT4D)
        return X_BTD
3.5.2 Embedding and Unembedding
Table of Contents (§3.5 Learning Representations with GPTs)
3.5.3 Optimizing Loss with AdamW on Cross Entropy
Table of Contents (§3.5 Learning Representations with GPTs)
Intermezzo Three: The Language of Neural Networks
I3.1 Sequences, Continuity, Limits, Derivatives
I3.2 The NETSOR Language
4. The Engine of Automatic Differentiation
The Age of Research, roughly spanning the time period of 2012-2019,
was a period which you’ve discovered, invented, and constructed for yourself
throughout Part I. Elements of Networks and Part II. Neural Networks which compose together into a unified coverage of both deep learning architecture and deep learning systems.
We have now built foundation in the art of tensor programs, specifically the tensor program of the transformer, which although is a single architecture variant, is extremely general across any domain which can be casted as autoregressive next-token prediction.
Although this is the final chapter where we evolve our implementation of borscht from a numerical library to a full-blown bateries included deep learning framework like torch,
let us briefly recall our journey that led us to this very moment.
After §1. Self-Supervised Sequence Learning with Single-Layer Networks and §3. Self-Supervised Pre-Training with Deep Networks,
we have now built foundation in the architecture of deep neural networks, which culminated in implementing the training and inference loops for nanogpt in §3.5 Learning Representations with GPTs.
First, we understand that language models such as nanogpt, Chat, and Claude
are evaluated as next-token predictors which although decide on a final classifying token for the given context (todo ?), have a step of inference by modeling language stochastically with a conditional random variable endowed with a probability distribution where such distribution corresponds to an array
which can be represented by a borscht.Tensor with .shape of (V).
This was the first step in our transition from classical software 1.0 to the jazz of software 2.0,
namely, by transitioning from variables to random variables in §1.1 From Certain to Uncertain Knowledge.
Second, we understanding that such language models probabilistically specified as autoregressive next-token predictors are implemented by estimating the parameterization of their functions with weights and bias so that where is a function that takes in a one-hot vector as input (expand, context?), evaluates the weighted sum with which is the standard inner product of the dot product, and then either uses the dot product directly in the case of linear regression with §1.3 Parameterizing Classification with Linear Regression or further composes the output with a squashing function in §1.4 Parameterizing Classification with Logistic Regression. In either case, both models are specified dimensionally with linear algebra and implemented with the optimization of differential calculus.
Third, we increased the expressivity of such implementations by transitioning from localist representations of one hot vectors to distributional representations of feature map . We started with a vanilla multi-layer perceptron also known as a feedforward neural net.
Fourth, we explored various inductive biases, exploring FFNs, CNNs, RNNs, culminating in GPTs with their core attention mechanism.
Moreover, after §2. The Parallelized Multidimensional Tensor,
we also have foundation in the systems of deep neural networks, which culminated in implementing the training and inference loops for nanogpt in §3.5 Learning Representations with GPTs.
First, layer -1
implemented our own borscht.Tensor
by §2.1 Virtualizing Shapes with Strides
and layer 0 §2.2 Accelerating Basic Linear Algebra on CPUs.
automatic differentiationautomatic differentiation optimizersoptimizers network primitivesnetwork primitives parallel programmingparallel programming massively parallel processorsmassively parallel processors graphics processing unit (GPU)GPU CUDA RustCUDA Rust PTXPTX SASSSASS
Finish strong young hacker.
4.1 Gradient-Based Optimization with Automatic Differentation
In which we implement the engine of automatic differentiation, the magic spell AI researchers cast to receive just from the specifcation of .
4.1.1 Symbolic, Numerical, and Algorithmic Differentiation
Lorem ipsum dolor sit amet,
consectetur adipiscing elit. Donec aliquam varius mi, pharetra scelerisque nulla vehicula ut. Cras ac faucibus dolor. Nunc tempus efficitur ultricies. Nullam non fermentum elit, et tincidunt ante. Donec hendrerit metus ac urna semper, in facilisis leo egestas. Integer sit amet quam ultrices, dapibus sem a, volutpat velit. Pellentesque eget ipsum consequat sem luctus blandit a et nibh. Mauris gravida felis ut dignissim volutpat. Quisque volutpat pulvinar enim in venenatis. Integer posuere tincidunt leo vel congue. Sed ex velit, posuere ut nibh nec, ultrices malesuada nibh. Fusce scelerisque mollis neque id fringilla. Etiam rhoncus quam a leo ultrices rutrum non vitae est. Donec bibendum, arcu sagittis consequat vestibulum, lectus elit bibendum libero, non rhoncus lorem lorem a neque. Sed ex felis, rutrum non consequat eget, tincidunt ac lacus.
4.1.2 Forward Mode
Consider the function where ,
and translate it to it’s computational counterpart in python with one-dimensional Tensors:
import picograd as pg

def f(x1: pg.Tensor, x2: pg.Tensor) -> pg.Tensor:
  a = pg.exp(x1)
  b = pg.sin(x2)
  c = b**2
  d = a*c
  return d
Figure 1. Python source for the function where
Here we’ve broken up the function to render the subexpressions more clearly.
But this isn’t necessary — automatic differentiation will work if the function was expressed in one line.
In part one, the development of picograd followed that of numpy —
an array programming language similar to Matlab but embedded in the host language of Python,
that could evaluate functions of the form
where Tensor objects stored their values with the value: field
and the function types that produced their values with Op.
For instance, evaluating the specified function f from above with 9 and 10
if __name__ == "__main__":
  print(f(9, 10))
populates the Tensor.value fields.
In part one of the book we verified this with a REPL-interface,
but we can also represent the entire expression being evaluated with a
graph of vertices and edges where the vertices are Tensors
(along with their Ops and values) and the edges are their data dependencies:
Here you can see that even if the function was specified in one line,
the graph of the expression always parses into Tensor vertices, and data dependency edges.
You may have noticed the Tensor.grad fields, which supposedly store the values of derivatives .
The question now remains in how to populate these fields.
Taking a step back to differential calculus, deriving the derivative of involves the application of the chain rule where . Evaluating the derivative of the function with respect to its inputs and results in
symbolic and numeric differentiattion symbolic differentiation has performance issues since a large unrolled expression must be constructed in order to differentiate[^0], whereas numerical differentiation has correctness issues since evaluating finite differences requires evaluating functions to a precision point resulting in numerical instability. (trace through EXAMPLE for both. talking nets widrow)
To populate the Tensor.grad fields, the simplest idea would be
to literally translate the manual derivation of the derivative into code.
The translation from math to code involves a design decision:
should we evaluate from outputs to inputs (symbolically outside-in, graphically right-to-left) or from inputs to outputs (symbolically inside-out, graphically left-to-right)?
Although the former order seems more natural with symbolic expressions,
there’s nothing illegal about the latter.
import picograd as pg

def f(x1: pg.Tensor, x2: pg.Tensor) -> pg.Tensor:
  a = pg.exp(x1)
  b = pg.sin(x2)
  c = b**2
  d = a*c
  return d

# dict[f(x), f'(x)] of local derivatives (adjoints)
dd_da, dd_dc = [c, a] # d(a,c):=a*c ==> d'(a)=c, d'(c)=a
da_dx1 = pg.exp(x1) # a(x1):=exp(x1) ==> a'(x1)=exp(x1)
dc_db = 2*b # c(b):=b^2 ==> c'(b)=2b
db_dx2 = pg.cos(x2) # b(x2):=sin(x2) ==> b'(x2)=cos(x2)

# outputs to inputs: outside-in symbolically, right-to-left graphically
dd_dd = pg.Tensor(1) # base case
dd_da, dd_dc = [dd_dd*dd_da, dd_dd*dd_dc]
dd_dx1 = dd_da*da_dx1 # DONE for the x1->d path

dd_db = dd_dc*dc_db
dd_dx1 = dd_db*db_dx2 # DONE for x2->path

# inputs to outputs: inside-out symbolically, left-to-right graphically
dx1_dx1, dx2_dx2 = [pg.Tensor(1), pg.Tensor(1)] # base case
da_dx1 = da_dx1*dx1_dx1
dd_dx1 = dd_da*da_dx1 # DONE for the x1->d path

db_dx2 = db_dx2*dx2_dx2
dc_dx2 = dc_dc*db_dx2
dd_dx2 = dd_dc*dc_dx_2 # DONE for the x2->d path
Do you notice any difference in the number of evaluations between the two orders?
4.1.3 Backward Mode
The outputs-to-input ordering takes 6 arithmetic operations (including the destructuring),
whereas the input-to-output ordering take 7 arithmetic operations.
This is because the former can reuse dd_dd
as a dynamic programming solution to a subproblem for the two inputs, whereas the latter cannot.
And taking a step back, we only want to reuse the output because the shape of the function
is of . Alternatively, if had type ,
then the input-to-output ordering would be able to reuse results.
This distinction is referred to as “forward-mode” vs “reverse-mode”, and reflects
the fact that for some function
the time complexity of forward-mode differentiation is proportional to ,
whereas that of forward-mode differentiation is proportional to .
If the expression graph fans-in so that , reverse-mode is preferred.
If the expression graph fans-out so that , forward-mode is preferred.
However, if we take a step with a graph-theory lens, we can see that the derivative is the sum of paths,
where each path is a product of local derivatives from the input source to the output sink.
From a combinatorics perspective, we are calculating all the possible (ors) ways (ands)
on how the inputs perturb the output. That is:
and as long as the operations along this path are associative — — then we can choose the order in how we perform these path products to minimize the number of operations. Finding the optimal ordering is an NP-hard problem because ____. For instance, if the expression graph is diamond-shaped, evaluating the derivative with forward-mode for the left-half and reverse-mode for the right-half would be more performant. In practice, we use reverse-mode as a heuristic, since most of the functions that are differentiated (so they can be optimized) in the field of machine learning are neural networks of the form
How can we generalize this into an algorithm?
All we need are 1. mappings from and 2. a topological sort
For the derivative rules, the same way that optimizing compilers implement an optimization “manually” once which then gets reused many times, the authors of deep learning frameworks also implement derivatives manually which then become reused many times through automatic differentiation. In theory, we can differentiate any expression with f’(x) with only a few derivative rules for addition and multiplication, but in practice most frameworks provide sugar for complex derivatives.
For topological sort, we can simply reversed the ordering produced by a depth-first-search:
def toposort(self):
  order: list[Op] = []
  visited: set[Op] = set()

  def dfs(node: Op) -> None:
    if node in visited: return
    visited.add(node)
    for src in node.src: dfs(src)
    order.append(node)

  dfs(self)
  return order

class Tensor():
  def backward():
    for t in reversed(topo):
      t.backward()
We will now use this idea to modify the interpretation of our deep learning framework to not only evaluate , but as well. This is done by dynamically overloading the operators at runtime[^0] to trace the expression graph
chain_rules = PatternMatcher([
  (Pattern(OpCode.MATMUL, name="input"), lambda output_grad, input: (_____,)),
  (Pattern(OpCode.MATVEC, name="input"), lambda output_grad, input: (_____,)),
  (Pattern(OpCode.RECIPROCAL, name="input"), lambda output_grad, input: (-output_grad * input * input,)),
  (Pattern(OpCode.SIN, name="input"), lambda output_grad, input: ((math.pi/2 - input.src[0]).sin() * output_grad,)),
  (Pattern(OpCode.LOG2, name="input"), lambda output_grad, input: (output_grad / (input.src[0] * math.log(2)),)),
  (Pattern(OpCode.EXP2, name="input"), lambda output_grad, input: (input * output_grad * math.log(2),)),
  (Pattern(OpCode.SQRT, name="input"), lambda output_grad, input: (output_grad / (input*2),)),
  (Pattern(OpCode.ADD), lambda output_grad: (1.0*output_grad, 1.0*output_grad)),
  (Pattern(OpCode.MUL, name="input"), lambda output_grad, input: (input.src[1]*output_grad, input.src[0]*output_grad)),
])

class Tensor:
  def _forward(self, f:Callable, *other:Tensor) -> Tensor: #extra_args=(), **kwargs)
    out_tensor = evaluator.eval_uop([self, other], out_uop)

  def backward(self, grad:Tensor|None=None) -> Tensor:
    """
    backward performs by collecting tensors, computing gradients with automatic differentiation, and updating said tensors.
    """
    # 1. collect all tensors that requires grad by topologically sorting the graph of uops and filter
    all_uops = self.uop.toposort()
    tensors_require_grad: list[Tensor] = [t for tref in all_tensors if (t:=tref()) is not None and t.uop in all_uops and t.requires_grad]
    uops_require_grad = [t.uop for t in tensors_require_grad]
    assert grad is not None or self.shape == tuple(), "when no gradient is provided, backward must be called on a scalar tensor"
    if not (self.is_floating_point() and all(t.is_floating_point() for t in tensors_require_grad)): raise RuntimeError("only float Tensors have gradient")

    # 2. compute the gradient with a map of tensors to partials
    if grad is None: grad = Tensor(1.0, dtype=self.dtype, device=self.device, requires_grad=False) # base case is 1.0
    tens2grads = Tensor._automatically_differentiate(self.uop, grad.uop, set(uops_require_grad)) # skipping materializing zerod grads for now
    grads = [Tensor(g, device=t.device) for t,g in zip(tens2grads.keys, tens2grads.values)] # initialize tensor grads on device

    # 3. update the tensors that require grad with the gradient's partials
    for t,g in zip(tensors_require_grad, grads):
      assert g.shape == t.shape, f"grad shape must match tensor shape, {g.shape!r} != {t.shape!r}"
      t.grad = g if t.grad is None else (t.grad + g) # accumulate if t.grad exists
    return self

  @staticmethod
  def _automatically_differentiate(root:Op, root_grad:Op, targets:set[Op]) -> dict[Op, Op]:
    """
    _differentiate backpropagates partials on a topologically sorted expression graph with the chain rule
    and produces the gradient in the form of a map of ops to their partials (which, in turn, are ops)
    """
    tens2grads = {root: root_grad}

    # 1. topological sort
    in_target_path: dict[Op, bool] = {}
    for u in root.toposort(): in_target_path[u] = any(x in targets or in_target_path[x] for x in u.src)
    dfs = list(root.toposort()) # lambda node: node.op not in {OpCode.DETACH, OpCode.ASSIGN} and in_target_path[node])) # don't flow through DETACH/ASSIGN or anything not in target path

    # 2. backpropagation with the chain rule
    for tensor in reversed(dfs):
      if tensor not in tens2grads: continue

      local_grads: tuple[Op|None, ...]|None = cast(tuple[Op, ...]|None, chain_rules.rewrite(tensor, ctx=tens2grads[tensor]))
      if local_grads is None: raise RuntimeError(f"failed to compute gradient for {tensor.op}\n\nin {str(tensor)[0:1000]}...")
      assert len(local_grads) == len(tensor.src), f"got {len(local_grads)} gradient, expected {len(tensor.src)}"

      for tensor,local_grad in zip(tensor.src, local_grads): # <--------------------- MOOOSE: why are we accumulating inside ad()? don't we do it in backward()??
        if local_grad is None: continue
        if tensor in tens2grads: tens2grads[tensor] = tens2grads[tensor] + local_grad # accumulate if tensor exists
        else: tens2grads[tensor] = local_grad # o/w initialize
To implement automatic differentiation with Tensor.backward(),
there is a design decision to be made
— the choice of implementing it dynamically or just-in-time[^3],
similar to the decision of how to implement types for general programming languages[^4].
This stands in contrast to the alternative of performing a just-in-time, source-to-source transformation.
Let’s now move onto automatically differentiating the functions of neural networks, specifically the FFN language model from earlier. (johnson/ryan adams ordering) n^2 vs n^3
4.1.4 Stochastic Gradient Descent
4.1.5 Adam
Table of Contents (§4.1 Automatic Differentiation)
4.2 Network Primitives
In which we …
4.2.1 Representing Models with Graph<borscht.Tensor>
4.2.2 Implementing Forward Pass for FFN
In which we implement the forward pass for class MLP(nn.Module)
with
borscht.nn.Embedding()
borscht.nn.Linear()
borscht.nn.Tanh()
missing notebook: /opt/build/repo/sitp/notebooks/4.1_makemore.ipynb
4.2.3 Implementing Forward Pass for CNN
4.2.4 Implementing Forward Pass for RNN
4.2.5 Implementing Forward Pass for GPT

missing notebook: /opt/build/repo/sitp/notebooks/4.1_makemore.ipynb
missing notebook: /opt/build/repo/sitp/notebooks/4.1_makemore.ipynb
4.3 From Sequential Machines to Parallel Machines
The opening call to adventure in Part I. Elements of Networks invited the programmers of Silicon Valley to take a similar journey between the tension of the finite and infinite that the Ancient Greeks took. That is, to contribute towards this new approach of augmenting and amplifying human intelligence, they must climb back down from their current pitch in programming algorithms of sets, maps, lists, trees, and graphs on serial machines to optimizing the distributions of scalars, vectors, matrices, tensors, and neural networks on massively parallel machines. Now is the time to add that final element. That of parallel programming on NVIDIA GPUs with CUDA Rust.

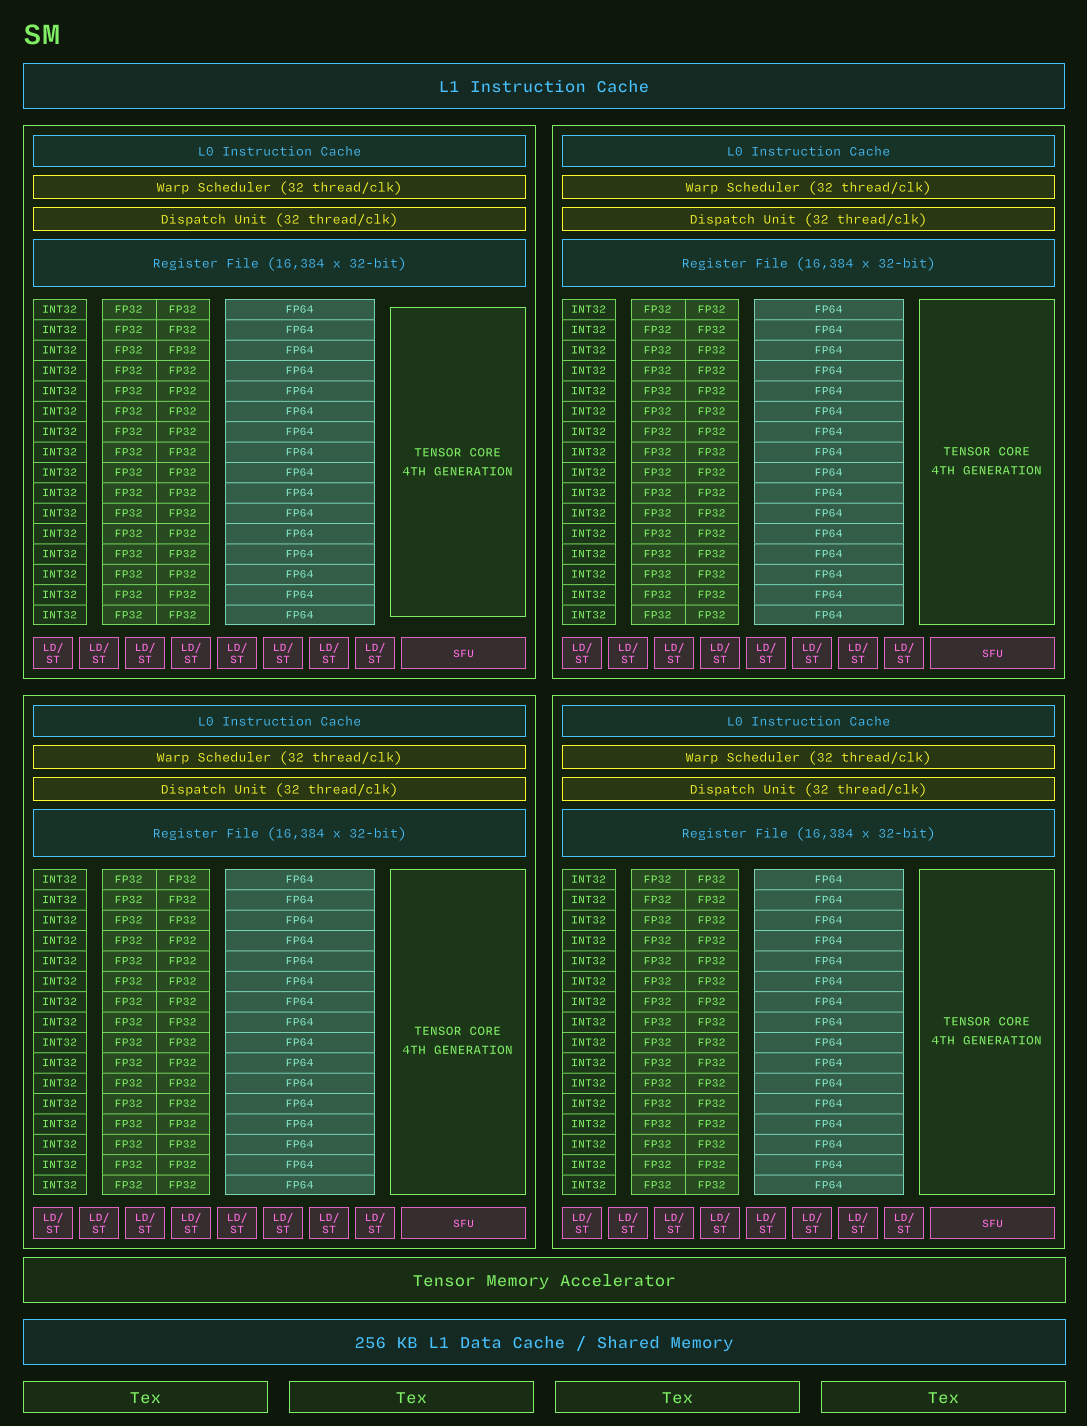
From Modal GPU Glossary (Streaming Multiprocessor), modified from a diagram in Fabien Sanglard’s blog, itself likely modified from a diagram in the CUDA C Programming Guide.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Donec aliquam varius mi, pharetra scelerisque nulla vehicula ut. Cras ac faucibus dolor. Nunc tempus efficitur ultricies. Nullam non fermentum elit, et tincidunt ante. Donec hendrerit metus ac urna semper, in facilisis leo egestas. Integer sit amet quam ultrices, dapibus sem a, volutpat velit. Pellentesque eget ipsum consequat sem luctus blandit a et nibh. Mauris gravida felis ut dignissim volutpat. Quisque volutpat pulvinar enim in venenatis. Integer posuere tincidunt leo vel congue. Sed ex velit, posuere ut nibh nec, ultrices malesuada nibh. Fusce scelerisque mollis neque id fringilla. Etiam rhoncus quam a leo ultrices rutrum non vitae est. Donec bibendum, arcu sagittis consequat vestibulum, lectus elit bibendum libero, non rhoncus lorem lorem a neque. Sed ex felis, rutrum non consequat eget, tincidunt ac lacus.

Nulla quis dictum diam, a cursus nibh. Pellentesque magna ante, lobortis a aliquam at, imperdiet eget magna. Nam pharetra dolor lectus, eu hendrerit ipsum tincidunt molestie. Cras eget viverra ipsum. Cras consequat metus quis nibh fermentum, egestas vestibulum odio lacinia. Donec ut ante hendrerit, convallis sem pulvinar, pulvinar magna. Etiam consequat mattis turpis non mollis. Sed consequat et sem quis interdum. Vivamus blandit elementum tortor non convallis. Duis quis nunc nisi. Fusce scelerisque felis pellentesque ex elementum imperdiet. Nulla facilisi. Nunc molestie urna sit amet nisl ullamcorper, at convallis augue tempor.
https://nvlabs.github.io/cuda-oxide/getting-started/hello-gpu.html#install-cargo-oxide
So with that all said and done, let us extend the mixed source of Python and Rust for borscht with a third language for the devicedevice.
Recall that in §2.1.1 From Virtual to Physical Machines we installed the Rust toolchain so that rustc could translate our program into the machine language of a physical processor. That toolchain is still necessary, but it is no longer sufficient, because the physical machine we are now targeting is not the one running our program. A GPU program is really two programs — the hosthost program which runs on the CPU and orchestrates memory and launches, and the devicedevice program of kernelskernels which runs on the GPU. The two are compiled by two different compilers, for two different instruction sets, and then stitched back together.
Historically the device half of that pair was written in CUDA C++ and compiled by NVIDIA’s nvcc, which meant that a Rust deep learning framework had to reach across a foreign function interface to say anything to the GPU at all. We will not do that. Instead we will keep host and device in the same file and the same language by way of cuda-oxidecuda-oxideSee NVlabs/cuda-oxide. It is explicitly alpha software: expect bugs and API breakage., a codegen backendcodegen backend for rustc which compiles functions annotated #[kernel] down to PTXPTX, the virtual instruction set of NVIDIA GPUsPTX is virtual in exactly the sense of §2.1.1 — it is not what the silicon executes. The driver finishes the job, lowering PTX to the SASSSASS of your particular chip at load time.. Note that this is the same turtle we met in Part I: rustc never emitted x86 directly either, it emitted LLVM. Here it emits LLVM too, only the backend of that backend is NVPTX instead of X86.
So the toolchain grows a device half:
| host | device | |
|---|---|---|
| compiler | rustc | rustc + rustc-codegen-cuda |
| target | x86-64, ARM, RISC-V | PTX → SASS |
| driver | cargo | cargo oxide |
| runtime | — | CUDA Toolkit + NVIDIA driver |
Concretely, you need five things. A Linux machine with an NVIDIA GPU and a driverdriver new enough for your toolkit. The CUDA ToolkitCUDA Toolkit (12.x or newer), which supplies nvcc, libNVVM, nvJitLink and libdevice. LLVM 21 or newer, whose llc performs the final lowering from LLVM IR to PTXThis floor is not negotiable for modern chips. The backend emits TMA, tcgen05 and WGMMA intrinsics that llc from LLVM 20 and earlier cannot lower — simple kernels may survive on an older llc, but anything Hopper or Blackwell will not.. Clang 21 with its development headers, because the host bindings are generated by bindgen, which loads libclang and wants clang’s own stddef.h. And a Rust nightly, pinned by rust-toolchain.toml, carrying the rust-src, rustc-dev and llvm-tools components — nightly because a codegen backend plugs into rustc’s own internals, which are not a stable interface.
That is a long enough list that the honest advice is to not install it by hand. The repository ships a development containerdevelopment container which pins every one of the five, so the only things your host must provide are the NVIDIA driver and the NVIDIA Container ToolkitInstalling the container toolkit is not quite the whole story: it must also be registered with the container runtime, via sudo nvidia-ctk runtime configure --runtime=docker followed by a daemon restart. Without that step --gpus=all has no runtime to bind to and the container starts with no GPU.. The CUDA Toolkit itself never touches your machine.
> root@machine ~/ $ git clone https://github.com/NVlabs/cuda-oxide.git
> root@machine ~/ $ devcontainer up --workspace-folder cuda-oxide
> root@machine ~/ $ devcontainer exec --workspace-folder cuda-oxide bash
Those with Nix may prefer nix develop, which gives the same guarantee by a different road. Those who insist on installing to the metal should consult the project’s installation chapter; the one step people trip on is LLVM, since most distributions do not package a version recent enough, and you will want llvm.sh:
> root@machine ~/ $ wget https://apt.llvm.org/llvm.sh && chmod +x llvm.sh && sudo ./llvm.sh 21
> root@machine ~/ $ llc-21 --version | grep nvptx
    nvptx      - NVIDIA PTX 32-bit
    nvptx64    - NVIDIA PTX 64-bit
However you arrive, the toolchain is driven by cargo oxide, a cargo subcommandcargo subcommand standing in the same relation to cargo that cargo stands to rustc. Inside the cuda-oxide repository it resolves through a workspace alias and works immediately; for a project of our own, such as borscht, it must be installed against the pinned nightly:
> root@machine ~/ $ cargo +nightly-2026-04-03 install --git https://github.com/NVlabs/cuda-oxide.git cargo-oxide
    Installing /usr/local/cargo/bin/cargo-oxide
     Installed package `cargo-oxide v0.2.1` (executable `cargo-oxide`)
Before writing a line of our own, ask it whether the machine is in order. cargo oxide doctor is the whole of the preceding discussion turned into a checklist, and it is worth reading line by line, because every entry is a piece of the pipeline we just described:
> root@machine ~/ $ cargo oxide doctor
cargo-oxide environment check
==============================
Rust nightly toolchain... ✓ rustc 1.96.0-nightly (55e86c996 2026-04-02)
rust-toolchain.toml... ✓ channel nightly-2026-04-03
Pinned toolchain active... ✓ nightly-2026-04-03-x86_64-unknown-linux-gnu
Required rustup components... ✓ rust-src, rustc-dev, rust-analyzer, clippy, rustfmt, llvm-tools
Codegen backend... - not built yet (run `cargo oxide setup`)
CUDA headers (cuda.h)... ✓ /usr/local/cuda/include/cuda.h
CUDA toolkit (nvcc)... ✓ Cuda compilation tools, release 13.0, V13.0.48
libNVVM (libnvvm.so)... ✓ libNVVM 2.0
nvJitLink (libnvJitLink.so)... ✓ nvJitLink 13.0
libdevice (libdevice.10.bc)... ✓ /usr/local/cuda/nvvm/libdevice/libdevice.10.bc
llc (LLVM)... ✓ Ubuntu LLVM version 21.1.8 (/usr/bin/llc-21)
clang / libclang resource dir... ✓ /usr/lib/llvm-21/lib/clang/21
NVIDIA driver / GPU... ✓ NVIDIA A100-SXM4-40GB (compute capability 8.0, driver 580.105.08)
cuda-gdb (optional)... ✓ /usr/local/cuda/bin/cuda-gdb
compute-sanitizer (optional)... ✓ Version 2025.3.0.0
✅ Environment looks good!
Two of those lines deserve a second look. The compute capabilitycompute capability 8.0 is the generation of the chip — sm_80 is Ampere, sm_90 Hopper, sm_100 Blackwell — and it is what decides which instructions are available to us in §4.4; you will meet it again as the thing that makes a kernel fast on one machine and illegal on another. And the codegen backend reported as not built yet is not an error: it is a compiler, rustc-codegen-cuda, and cargo oxide will build and cache it for you on first use.
Now we can scaffold, exactly as maturin new scaffolded the Python and Rust halves of borscht back in §2.1.2:
> root@machine ~/ $ cargo oxide new borscht-cuda
✓ Created cuda-oxide project 'borscht-cuda'

  cd borscht-cuda
  cargo oxide doctor
  cargo oxide run

> root@machine ~/ $ cd borscht-cuda && ls
Cargo.toml
README.md
rust-toolchain.toml
src
[package]
name = "borscht-cuda"
version = "0.1.0"
edition = "2024"

[workspace]

[dependencies]
cuda-device = { git = "https://github.com/NVlabs/cuda-oxide.git" }
cuda-host = { git = "https://github.com/NVlabs/cuda-oxide.git" }
cuda-core = { git = "https://github.com/NVlabs/cuda-oxide.git" }
[toolchain]
channel = "nightly-2026-04-03"
components = [
    "rust-src",
    "rustc-dev",
    "rust-analyzer",
    "clippy",
    "rustfmt",
    "llvm-tools",
]
The three dependencies partition the problem the same way the machine does. cuda-device is the vocabulary of the device — #[kernel], thread::index_1d(), the indexing types — and it is the crate whose code rustc-codegen-cuda will consume. cuda-core is the host-side runtime of contexts, streams and buffers. cuda-host supplies #[cuda_module], the macro that welds the two halves together by embedding the compiled device artifact into the host binary and generating a typed launch method for each kernel. And the pinned rust-toolchain.toml is what makes the earlier +nightly-2026-04-03 unnecessary from here on: rustup reads it and selects the toolchain on every cargo invocation, fetching llvm-tools on first use.
The generated src/main.rs is the smallest complete example of the shape all of our kernels will take, and it repays a careful reading before we write our own:
use cuda_device::{kernel, launch_bounds, launch_contract, thread, DisjointSlice};
use cuda_host::cuda_module;
use cuda_core::{CudaContext, DeviceBuffer, LaunchConfig1D};

#[cuda_module]
mod kernels {
    use super::*;

    #[kernel]
    #[launch_bounds(256)]
    #[launch_contract(domain = 1, block = (256, 1, 1))]
    pub fn vecadd(a: &[f32], b: &[f32], mut c: DisjointSlice<f32>) {
        let idx = thread::index_1d();
        let idx_raw = idx.get();
        if let Some(c_elem) = c.get_mut(idx) {
            *c_elem = a[idx_raw] + b[idx_raw];
        }
    }
}

fn main() -> Result<(), Box<dyn std::error::Error>> {
    let ctx = CudaContext::new(0)?;
    let stream = ctx.default_stream();

    const N: usize = 1024;
    let a_host: Vec<f32> = (0..N).map(|i| i as f32).collect();
    let b_host: Vec<f32> = (0..N).map(|i| (i * 2) as f32).collect();

    let a_dev = DeviceBuffer::from_host(&stream, &a_host)?;
    let b_dev = DeviceBuffer::from_host(&stream, &b_host)?;
    let mut c_dev = DeviceBuffer::<f32>::zeroed(&stream, N)?;

    // SAFETY: this package owns the embedded device bundle produced for the
    // kernels module above.
    let module = unsafe { kernels::load(&ctx)? };
    let prepared = module.prepare_vecadd(LaunchConfig1D::new((N as u32).div_ceil(256), 256, 0))?;
    module.vecadd(&stream, &prepared, &a_dev, &b_dev, &mut c_dev)?;

    let c_host = c_dev.to_host_vec(&stream)?;
    println!("{:?}", &c_host[..5]);
    Ok(())
}
Everything above the fn main runs on the GPU and everything below it runs on the CPU, in one file, in one language, built by one command. Notice that the ownership we learned in Part I has followed us across the bus: a_dev and b_dev are borrowed immutably by the launch while c_dev is borrowed mutably, and the DisjointSlice<f32> in the kernel signature is the device-side statement that no two threads will write the same element. The data race that is the traditional first lesson of GPU programming is here a borrow checkerborrow checker error.
Building it will take a moment the first time, because cargo oxide must build the codegen backend before it can build anything with it:
> root@machine ~/ $ cargo oxide run
Building rustc-codegen-cuda backend...
    Finished `dev` profile [unoptimized + debuginfo] target(s) in 1m 06s
✓ Backend built: .../librustc_codegen_cuda.so
Detected GPU arch: sm_80 (via nvidia-smi)
    Finished `release` profile [optimized] target(s) in 22.04s
     Running `target/release/borscht-cuda`
[0.0, 3.0, 6.0, 9.0, 12.0]
Four numbers added on a hundred billion transistors. It is not much, but every matrix multiplication in §4.4 is that same skeleton with a better kernel inside it, and it is worth knowing two more subcommands before we go there, since we will lean on both: cargo oxide inspect prints the PTX that came out the far end of the pipeline, and cargo oxide pipeline prints every intermediate along the way, from Rust MIR through dialect-mir and LLVM IR to PTX. When a kernel is slow or wrong, that is where you look.
GPU MODE Lecture 3: Getting Started With CUDA for Python Programmers
GPU MODE Lecture 5: Going Further with CUDA for Python Programmers
GPU MODE Lecture 2: Ch1-3 PMPP book
GPU MODE Lecture 4: Compute and Memory Basics (Ch4-5 PMPP)
#![allow(unused)]
fn main() {
enum Device {
    Cpu,
    Gpu
}

enum Dtype {
    Float64(f64),
    Float32(f32),
    Float16(f16),
    Bfloat16(bf16),
}

struct Tensor {
    shape: Vec<u8>,
    stride: Vec<u8>,
    device: Device,
    dtype: Dtype,
    storage: Vec<Dtype>
}
}
4.4 Accelerating Matrix Multiplication on GPUs
In which we …
4.3.1 From Multi Core CPUs to Many Core GPUs
#![allow(unused)]
fn main() {
// gpu_host.rs
use cudarc::{driver::{self, PushKernelArg}, nvrtc};
use src_device::T; // shared type with device code
static PTX: &str = include_str!(concat!(env!("OUT_DIR"), "/gpu_device.ptx")); // Embed the PTX code as a static string.

pub fn cudars_helloworld() -> Result<(), Box<dyn std::error::Error>> {
  // initialize device context and stream via driver api
  let process = driver::CudaContext::new(0)?; // device 0
  let queue = process.default_stream();

  // load ptx via nvrtc
  let dylib = process.load_module(nvrtc::Ptx::from_src(PTX))?;
  let add_kernel = dylib.load_function("add")?;

  // allocate on device
  let (a, b): ([T; _], [T; _]) = ([1.0, 2.0, 3.0, 4.0], [2.0, 3.0, 4.0, 4.0]);
  let (a_gpu, b_gpu, mut c_gpu) = (queue.clone_htod(&a)?, queue.clone_htod(&b)?, queue.alloc_zeros::<T>(a.len())?);
  let (a_len, b_len) = (a_gpu.len(), b_gpu.len());

  let cfg = driver::LaunchConfig { grid_dim: (1, 1, 1), block_dim: (4, 1, 1), shared_mem_bytes: 0, };
  unsafe {
    queue
    .launch_builder(&add_kernel).arg(&a_gpu).arg(&a_len).arg(&b_gpu).arg(&b_len).arg(&mut c_gpu)
    .launch(cfg)?;
  }
  queue.synchronize()?;

  let c = queue.clone_dtoh(&c_gpu)?;
  println!("c from cuda is = {:?}", c);
  Ok(())
}
}
#![allow(unused)]
fn main() {
// gpu_device.rs
use cuda_std::kernel;
use crate::T;
#[allow(improper_ctypes_definitions)]
#[kernel] pub unsafe fn add(a: &[T], b: &[T], c: *mut T) {
let i = cuda_std::thread::index_1d() as usize;
if i < a.len() {
let elem = unsafe { &mut *c.add(i) };
*elem = a[i] + b[i];
}
}
#[allow(improper_ctypes_definitions)]
#[kernel] pub unsafe fn saxpy(a: &[T], b: &[T], c: *mut T) {
let i = cuda_std::thread::index_1d() as usize;
todo!()
}
#[allow(improper_ctypes_definitions)]
#[kernel] pub unsafe fn smul(a: &[T], b: &[T], c: *mut T) {
let i = cuda_std::thread::index_1d() as usize;
todo!()
}
#[allow(improper_ctypes_definitions)]
#[kernel] pub unsafe fn stanh(a: &[T], b: &[T], c: *mut T) {
let i = cuda_std::thread::index_1d() as usize;
todo!()
}
}